
Where should an intrusion detection system be placed?
Place intrusion detection sensors where they can observe traffic crossing trust boundaries and moving toward critical assets: typically at the network perimeter, between important internal segments, and within cloud or host environments where network visibility is limited. There is rarely one ideal location. The right combination depends on which traffic reaches each sensor, what remains encrypted, and who will investigate the alerts.
A perimeter sensor may show attempts to reach an application while missing an attacker moving from a compromised workstation to a database. Conversely, a sensor beside the database may see suspicious connections without showing how the attacker entered. For a project team, the placement decision is therefore a coverage and operating-capacity decision, not simply a choice of appliance location.
Start with the traffic you need to see
Before selecting sensor locations, identify the assets and attack paths that matter to the project. A current network diagram is useful, but it may not show the routes taken by production traffic, cloud services, remote users, or administrative connections. Ask application and network owners to confirm those flows against routing, firewall, and cloud configuration records.
For each important service, trace connections from their likely sources to the destination. Include user access, application-to-database traffic, management access, third-party connections, and routes between sites or cloud environments. Mark the boundaries between systems with different levels of trust or operational ownership. These crossings are candidates for monitoring because they expose activity moving into sensitive areas.
Then define the questions a sensor should help answer. Is the priority to detect hostile traffic entering an internet-facing environment, unusual access to a payment system, or movement between an office network and an operational technology segment? A location is useful only if the necessary traffic actually passes through it and the detection method can interpret enough of that traffic.
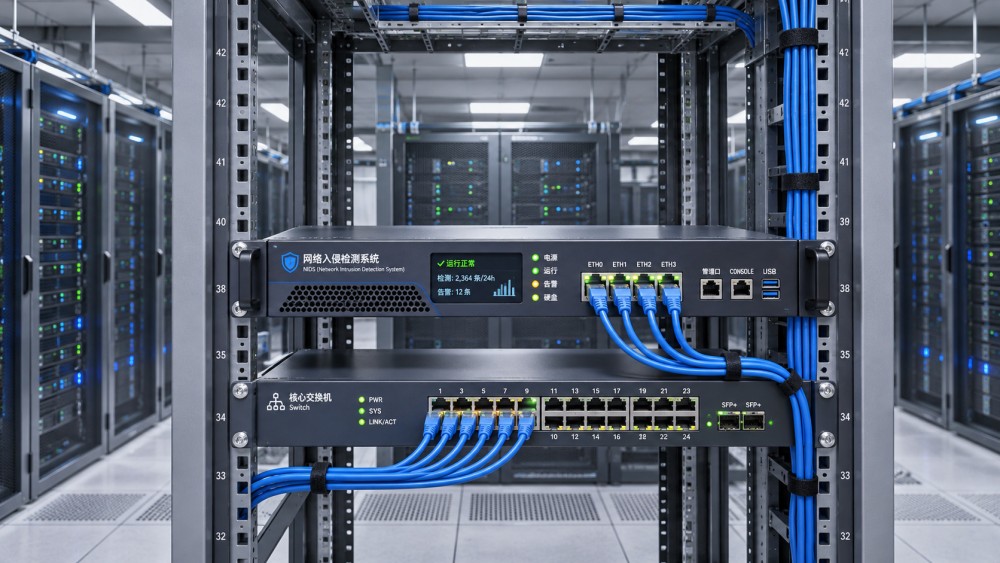
Choose locations according to the risk and visibility gained
Internet and external connection boundaries
A network intrusion detection sensor can monitor traffic entering or leaving an internet connection, a partner link, or another external boundary. It is useful for observing attempted exploitation, suspicious outbound connections, and traffic involving exposed services. The precise side of a firewall matters.
Outside the firewall, the sensor can see traffic that the firewall would otherwise block. This helps teams understand the volume and character of external attempts, but it can also create substantial alert noise. Inside the firewall, it sees traffic that has passed the firewall and may be closer to the activity requiring investigation. It will not show the blocked traffic, and either location can miss a connection that takes another route.
Document whether the goal is awareness of attempted attacks or detection of traffic that reached an internal environment. Some organizations monitor both sides, but each feed requires capacity, correlation, and an owner. Do not assume that observing the internet edge covers remote access, direct cloud connectivity, or separate partner circuits.
Between internal segments
Internal placement is valuable when the concern is lateral movement: activity traveling between systems after an initial compromise. Candidate locations include links between user networks and server networks, application and database tiers, privileged administration zones, or separate business units.
Prioritize a boundary through which access to a critical service normally passes. A sensor on a shared backbone may observe more traffic, but a strategically chosen segment boundary can produce more relevant alerts and make the source and destination easier to interpret. Confirm that routing and segmentation policies actually direct the intended flows through that point; an alternate path can make an apparently well-placed sensor ineffective.
For operational technology, monitoring the connection between enterprise and industrial networks can reveal unexpected cross-boundary activity. It will not necessarily show communications within a control network. Additional passive visibility may be needed there, subject to asset-owner approval, protocol support, and production availability requirements. Avoid introducing active scanning or other changes merely to validate a passive deployment without an agreed safety review.
Near critical workloads and hosts
A sensor close to a sensitive application can provide context about access to that service, especially when the perimeter carries too much unrelated traffic. The trade-off is scope: one workload-level sensor may not observe activity elsewhere. Redundant application instances, failover paths, and traffic distributed across multiple nodes must be included in the design.
Host-based intrusion detection can complement network monitoring by observing selected events on a server or endpoint, such as process activity, file changes, or security logs. It can be particularly useful when traffic is encrypted end to end. Host agents also introduce deployment, compatibility, performance, maintenance, and tamper-resistance considerations. Define which systems can support an agent and who will maintain it before counting on that coverage.
Cloud and virtual environments
Cloud workloads may exchange traffic without crossing an on-premises sensor. Place monitoring within the relevant virtual network or workload environment when the provider and architecture support it. Traffic mirroring, flow records, cloud audit events, and host telemetry can each contribute different evidence; they are not interchangeable.
Check whether the chosen mechanism covers traffic between workloads, across virtual network boundaries, and to managed services. Availability can vary by service, region, instance type, and configuration. Also establish where copied traffic and logs will be stored, which team controls access, and whether cross-account or cross-region collection introduces cost or data-location constraints.
Check what reaches the sensor before approving the design
A location on a diagram is not proof of visibility. Network-based Intrusion Detection Systems commonly receive a copy of traffic from a network tap, a switch mirror port, or a cloud traffic-mirroring mechanism. Confirm that the feed includes the required interfaces, VLANs, directions, and traffic types. Where traffic follows different forward and return paths, the sensor may see only part of a session.
Traffic volume is another placement constraint. Mirroring a busy link to an undersized sensor can result in dropped packets, incomplete sessions, and missed detections. Ask the network team for representative utilization, including peaks and expected growth, and verify the capacity of both the copying mechanism and the sensor. A sensor that reports healthy status while dropping traffic does not provide the intended control.
Encrypted traffic needs an explicit decision. A passive network sensor generally cannot inspect encrypted application content without access to suitable decrypted traffic or keys. Depending on the architecture and authorized controls, teams may place it at an approved decryption point, use endpoint or application telemetry, or detect from observable metadata and connection patterns. Each choice has different privacy, security, and operational implications; do not assume decryption is available or appropriate.
Turn the placement map into a deployable project
For each proposed monitoring point, record the protected asset or traffic path, the threat or behavior of interest, the feed source, the expected visibility limits, and the team responsible for triage. Add dependencies such as switch configuration, cloud permissions, rack space, licensing, log ingestion, and retention. This makes it easier to identify a sensor that looks valuable on paper but has no feasible feed or operating owner.
- Agree on an initial scope. Select the highest-priority flows and identify which are already covered by existing network, host, or cloud telemetry. Record gaps rather than assuming every environment can be monitored in the first release.
- Confirm implementation access. Obtain the network changes, cloud permissions, maintenance windows, and security approvals required to copy traffic and connect the sensor to alerting and case-management systems.
- Deploy in a controlled phase. Validate connectivity, time synchronization, traffic volume, and sensor health before enabling a broad set of detections. Preserve a rollback plan for infrastructure changes.
- Test the intended paths. Use authorized, agreed test traffic or simulations to verify that activity on each selected route is visible and that relevant alerts reach the assigned team. Coordinate tests with service owners.
- Review and tune. Investigate recurring noise, refine rules or exclusions, and retest after changes. Avoid suppressing an alert solely because it is frequent; first establish whether it represents expected activity or a real exposure.
Acceptance criteria should cover more than installation. For example, require evidence that named traffic paths are observed, sensor health and packet loss are monitored, alerts reach the agreed destination, and responders can identify the affected asset. Document test scope and results: a successful simulation demonstrates visibility for that activity under those conditions, not detection of every possible intrusion.
Plan for alerts after the project handover
Detection coverage has an operating cost. Estimate ingestion and retention needs alongside sensor licensing, infrastructure, integration, and analyst time. A broad placement that produces alerts no one can review may be less useful than a narrower deployment with reliable triage and a clear escalation route.
Agree on alert ownership across network operations, security operations, cloud teams, and application owners. The response procedure should identify who investigates, how asset context is obtained, when an incident is escalated, and who can authorize containment. An intrusion detection system reports or records suspicious activity; blocking generally requires a separate control or an explicitly integrated response workflow.
Finally, treat network changes as a trigger to reassess placement. A new cloud connection, migrated application, revised firewall route, or encrypted service can move traffic away from an existing feed or reduce what the sensor can interpret. Include monitoring owners in change review, and repeat targeted visibility tests when a critical traffic path changes.
Want to dive deeper into these market dynamics, or need data-driven support for your next business move? Drop a line below and let the analysts at CyberTrade provide customized insights.
Related News
 Identity AccessIs Cloud-Hosted RADIUS a Good Fit for Multicloud Enterprises?Posted on Nov 18, 2026Is a cloud-hosted RADIUS server a good fit for a multicloud enterprise? Explore integration, security, resilience, and costs before you decide.
 Identity AccessHow to Test RADIUS Failover Across Cloud RegionsPosted on Nov 18, 2026How do we test RADIUS failover across cloud regions? Follow a practical guide to verify recovery, secure access, audit logs, and failback.
 Identity AccessHow to Choose a Certificate Authority for Multicloud WorkloadsPosted on Nov 18, 2026How do we choose a certificate authority for workloads across multiple clouds? Explore key criteria, compare CA options, and plan a production-ready pilot.
 Multi-CloudHow to Verify CASB Visibility Across Multiple CloudsPosted on Nov 18, 2026How can we verify a CASB's visibility across multiple clouds? Learn to test coverage, trace events, uncover blind spots, and build a reliable assessment.
 Cloud SecurityHow to Test WAF Attack Blocking Without Disrupting Legitimate TrafficPosted on Nov 18, 2026How do we test whether a WAF blocks attacks without disrupting legitimate traffic? Explore safe simulations, false-positive checks, and staged enforcement.
 Identity AccessCan Smart Cards Work With Cloud Apps Without Replacing Your IdP?Posted on Nov 18, 2026Can smart cards work with cloud applications without replacing our identity system? Discover the integration requirements, security benefits, and pilot checks.
 Prices & CostsHow to Compare Cloud HSM Total Costs Across ProvidersPosted on Nov 18, 2026How do we compare the total cost of cloud HSMs across providers? Discover the hidden charges, key assumptions, and practical steps for a fair comparison.
 Multi-CloudHow to Verify Consistent API Gateway Authentication Across CloudsPosted on Nov 18, 2026Verify API gateway authentication across clouds with practical tests for tokens, routes, bypass risks, and policy enforcement. Explore the guide.
 Cloud SecurityDo You Need a Next-Generation Firewall in Every Cloud?Posted on Nov 18, 2026Do we need a next-generation firewall in every cloud environment? Explore traffic risks, cloud-native controls, costs and deployment options.
 Threat ResponseHow to Tell If a Cloud IDS Is Missing TrafficPosted on Nov 18, 2026How can we tell whether an IDS is missing traffic in a cloud environment? Compare flow evidence, test sensor visibility, and uncover hidden coverage gaps.
 Identity AccessHow to check if a certificate authority is trustedPosted on Nov 18, 2026Certificate Authorities aren't trusted equally everywhere. Learn how to check certificate chains, trust stores, and revocation before choosing a CA.
 Cloud SecurityCan cloud access security brokers detect shadow IT?Posted on Nov 18, 2026Cloud Access Security Brokers can uncover shadow IT—but visibility has limits. Discover how CASBs detect cloud apps, expose blind spots, and guide a practical response.











