
API Gateways for Microservices: Routing, Authentication and Rate Limits
API gateways for microservices can simplify how applications route requests, authenticate users and services, and enforce rate limits—but their effectiveness depends on configuration, integration, and operational oversight. Choosing one means balancing security requirements with delivery timelines, system compatibility, and ongoing support costs. The difficult decisions are rarely about whether a gateway has a feature; they are about where that feature applies, how it fails, and who maintains it after launch.
Start with the traffic, not the gateway
A gateway usually sits between clients and backend services, providing a controlled entry point for API requests. It can select a destination, validate credentials, apply traffic policies, and produce operational records. Depending on the architecture, an organization may use separate gateways for public APIs, partner integrations, or internal consumers.
Before selecting software, map the paths requests actually take. A customer-facing mobile application, a supplier integration, and an internal batch job may call the same service with different identities, availability expectations, and traffic patterns. They should not automatically inherit the same policy merely because they share an endpoint.
The map should also show paths that bypass the gateway. If a workload can reach a backend directly, authentication at the edge does not protect that path. Network controls, workload identity, and service-level authorization may still be required. Likewise, an API gateway is not automatically a replacement for a web application firewall or a service mesh: those tools address overlapping but different parts of the traffic and security problem.
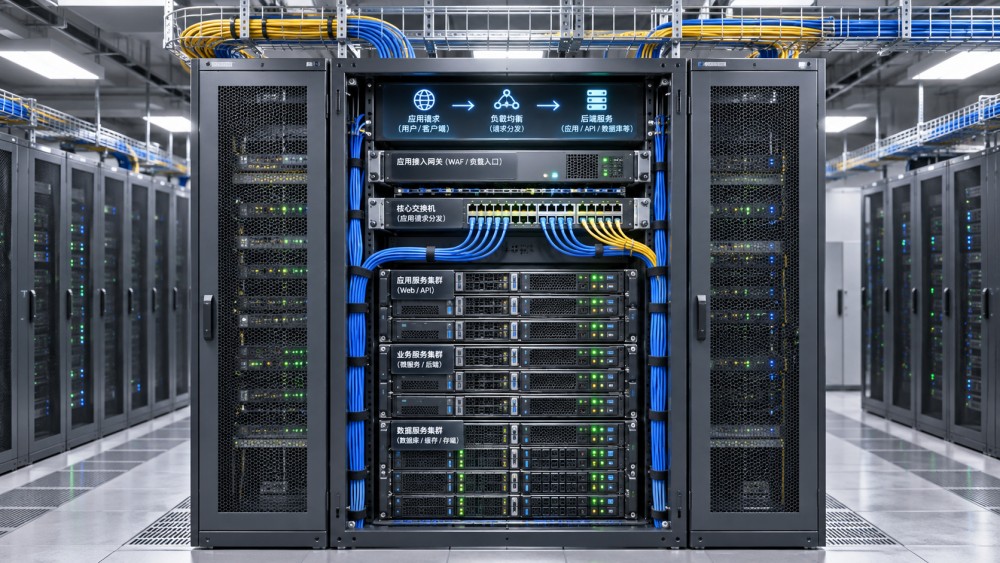
For a project plan, identify the owner of each boundary: who publishes routes, who approves authentication changes, who sets consumption limits, and who is called when a dependency fails. These decisions are easier to make before several application teams rely on the same gateway.
Routing decisions affect releases and recovery
Routing is more than matching a URL to a service. Teams may need to direct requests by hostname, path, header, API version, or deployment environment. A gateway can also help move a portion of traffic to a new service version, provided the chosen implementation supports the required rules and the team can observe and reverse the change.
Consider a migration from a legacy order API to a new service. The public interface may need to remain stable while the backend changes. The project should test not only a successful request but also timeouts, malformed responses, long-running operations, and the behavior of existing clients that cannot be upgraded immediately. A route that works in a demonstration can still break a partner integration if headers, response codes, or paths change unexpectedly.
Retries deserve particular scrutiny. Retrying an interrupted read may be acceptable; retrying a payment or order submission without an idempotency mechanism can create duplicate actions. Establish which component retries, which operations are safe to repeat, and how timeout budgets are divided between the client, gateway, and backend. Otherwise, each layer may wait or retry independently while the user sees only a stalled transaction.
For high-availability services, ask what happens when a gateway instance, control plane, configuration store, or network link becomes unavailable. Managed and self-hosted deployments divide those responsibilities differently. A documented rollback and a tested failure procedure are more useful than a generic promise of resilience.
Authentication at the edge is not complete authorization
Centralizing authentication can reduce repeated work across services. A gateway may validate a token issued by an identity provider, check its intended audience and expiry, and reject requests that do not meet an API’s entry requirements. For machine clients, it may support certificates or other credentials, depending on the deployment.
The integration details determine whether this works in production. Confirm how signing keys are discovered and rotated, how clock differences are handled, and what happens when the identity provider or key endpoint is temporarily unreachable. A cached validation key may preserve availability in some designs, but the team must understand the security and operational consequences of its cache and revocation behavior.
Do not treat a valid token as permission to perform every action. The gateway can enforce broad checks, such as whether a caller has a required scope, while the backend typically remains responsible for decisions tied to business data: whether this particular user can view this account, for example. The exact division should be documented and tested so that neither layer assumes the other has made the check.
Identity propagation is another common fault line. If the gateway forwards user or tenant information in headers, backends must receive those headers only from trusted sources. The gateway should remove or overwrite client-supplied versions, and network or service authentication controls should prevent an untrusted caller from impersonating the gateway. Where services call one another, agree on whether they forward the original user context, use their own workload identity, or require both.
Operational ownership matters here as much as protocol support. Credential enrollment, service-account rotation, emergency access, and removal of departing partners all need an accountable team. A gateway cannot repair an identity lifecycle that no one owns.
Rate limits should protect a specific constraint
Rate limiting is often described as a single switch, but the useful question is: what is being protected? A public endpoint may need protection from abusive traffic; an expensive search operation may need to protect a database; a partner API may need a contractual consumption policy. Each can require a different limit and a different key.
A limit based only on source IP can penalize unrelated users behind a shared network or be ineffective when callers use many addresses. Depending on the scenario, a policy may need to identify an authenticated client, tenant, credential, or route. An anonymous endpoint may still require IP-based controls, but that is a design choice with known trade-offs, not a universal answer.
Test bursts as well as average traffic. A scheduled integration can generate a legitimate spike, while a slow stream of costly requests can exhaust a backend without triggering a simple request-count limit. Concurrency limits, timeouts, quotas, and backend capacity controls may be needed alongside request rates. When callers exceed a limit, the response should be predictable, and client teams need to know whether and when to retry.
Distributed enforcement adds another question: is the counter shared across instances and regions, or maintained locally? The answer affects consistency, latency, and behavior during a network partition. Ask the supplier to demonstrate what happens when the counter store is unavailable and whether the policy fails open or closed. Either choice can be defensible; neither should be discovered during an incident.
Make the pilot prove the operating model
A useful pilot includes one real integration with a representative client, identity provider, and backend—not just a synthetic request to a sample service. Choose a scope small enough to reverse, but complicated enough to expose dependencies. A partner-facing read API is often easier to begin with than a transaction path whose failure affects revenue or safety.
Agree on acceptance criteria before the pilot starts. The following checks turn broad requirements into evidence a delivery team can review:
- Demonstrate that valid callers reach the intended backend and that invalid, expired, or incorrectly scoped credentials are rejected according to the agreed policy.
- Show how a route or policy change is reviewed, deployed, audited, and rolled back, including who can make an emergency change.
- Run a representative load and burst test against agreed backend capacity; record the workload, observation period, error rate, and latency measurement points.
- Interrupt relevant dependencies in a safe test environment and document observed behavior, recovery steps, and any manual intervention.
- Trace a request across the gateway and backend without exposing tokens, sensitive payloads, or unnecessary personal information in logs.
A passing test should be tied to its conditions. Results from a single region, a short observation window, or a limited identity configuration do not establish performance for every future workload. Record what was excluded and assign a date or milestone for testing it.
Budget for the dependencies that remain after launch
License or managed-service charges are only part of the decision. Include deployment engineering, identity integration, certificate management, monitoring, log ingestion and retention, policy maintenance, training, support, and eventual migration. Check whether capabilities needed for the design require a particular edition, external component, or additional service.
In multicloud environments, a common policy description does not guarantee identical behavior across providers or regions. Teams need to verify configuration delivery, traffic handling, telemetry location, and the practical process for investigating an issue that crosses those boundaries. For critical infrastructure, changes may also depend on maintenance windows, legacy client compatibility, and a clear separation between enterprise and operational responsibilities.
Before committing to a rollout date, obtain a route inventory, named policy owners, a tested rollback path, and a support plan for the first production integration. If any of those are missing, the remaining work is not merely configuration: it is part of the delivery scope and should be visible in the schedule.
Want to dive deeper into these market dynamics, or need data-driven support for your next business move? Drop a line below and let the analysts at CyberTrade provide customized insights.
Related News
 Identity AccessIs Cloud-Hosted RADIUS a Good Fit for Multicloud Enterprises?Posted on Nov 18, 2026Is a cloud-hosted RADIUS server a good fit for a multicloud enterprise? Explore integration, security, resilience, and costs before you decide.
 Identity AccessHow to Test RADIUS Failover Across Cloud RegionsPosted on Nov 18, 2026How do we test RADIUS failover across cloud regions? Follow a practical guide to verify recovery, secure access, audit logs, and failback.
 Identity AccessHow to Choose a Certificate Authority for Multicloud WorkloadsPosted on Nov 18, 2026How do we choose a certificate authority for workloads across multiple clouds? Explore key criteria, compare CA options, and plan a production-ready pilot.
 Multi-CloudHow to Verify CASB Visibility Across Multiple CloudsPosted on Nov 18, 2026How can we verify a CASB's visibility across multiple clouds? Learn to test coverage, trace events, uncover blind spots, and build a reliable assessment.
 Cloud SecurityHow to Test WAF Attack Blocking Without Disrupting Legitimate TrafficPosted on Nov 18, 2026How do we test whether a WAF blocks attacks without disrupting legitimate traffic? Explore safe simulations, false-positive checks, and staged enforcement.
 Identity AccessCan Smart Cards Work With Cloud Apps Without Replacing Your IdP?Posted on Nov 18, 2026Can smart cards work with cloud applications without replacing our identity system? Discover the integration requirements, security benefits, and pilot checks.
 Prices & CostsHow to Compare Cloud HSM Total Costs Across ProvidersPosted on Nov 18, 2026How do we compare the total cost of cloud HSMs across providers? Discover the hidden charges, key assumptions, and practical steps for a fair comparison.
 Multi-CloudHow to Verify Consistent API Gateway Authentication Across CloudsPosted on Nov 18, 2026Verify API gateway authentication across clouds with practical tests for tokens, routes, bypass risks, and policy enforcement. Explore the guide.
 Cloud SecurityDo You Need a Next-Generation Firewall in Every Cloud?Posted on Nov 18, 2026Do we need a next-generation firewall in every cloud environment? Explore traffic risks, cloud-native controls, costs and deployment options.
 Threat ResponseHow to Tell If a Cloud IDS Is Missing TrafficPosted on Nov 18, 2026How can we tell whether an IDS is missing traffic in a cloud environment? Compare flow evidence, test sensor visibility, and uncover hidden coverage gaps.
 Identity AccessHow to check if a certificate authority is trustedPosted on Nov 18, 2026Certificate Authorities aren't trusted equally everywhere. Learn how to check certificate chains, trust stores, and revocation before choosing a CA.
 Cloud SecurityCan cloud access security brokers detect shadow IT?Posted on Nov 18, 2026Cloud Access Security Brokers can uncover shadow IT—but visibility has limits. Discover how CASBs detect cloud apps, expose blind spots, and guide a practical response.











