
Signature vs. Anomaly-Based Network Intrusion Detection Systems
Signature-based intrusion detection is generally the stronger choice when the priority is to recognize documented attack patterns with explainable rules. Anomaly-based detection can expose suspicious behavior that does not match a known signature, but its value depends on representative network data, an appropriate baseline, and the capacity to investigate deviations that are not attacks.
The choice is rarely a clean separation between known and unknown threats. A signature can describe a broad malicious behavior rather than one specific exploit, while an anomaly detector can miss an attack that resembles normal activity. The decisive question is which method can observe the relevant traffic and produce actionable evidence under the network’s actual operating conditions.
What each detection method is really comparing
A signature-based network intrusion detection system compares observed traffic or reconstructed protocol activity against predefined conditions. A rule might look for a recognizable exploit sequence, a suspicious protocol field, a known command pattern, or a combination of network attributes. The matching logic can be narrow and precise or broad enough to cover variations of an attack.
That distinction matters when evaluating claims about “known threats.” A system does not necessarily need an exact byte-for-byte match to detect a variant. Conversely, a rule written for a particular protocol, encoding, or application version can fail when the attacker changes how the activity appears on the wire. Coverage depends on the rule logic, protocol parsing, configuration, and the traffic available to the sensor—not simply on the number of signatures supplied.
Anomaly-based detection compares observed behavior with an expected pattern. Depending on the implementation, that expectation may come from statistical thresholds, learned models, peer-group comparisons, or manually defined behavioral policies. A system might flag a server communicating with an unusual destination, an unexpected increase in outbound data, or a device using a protocol outside its normal role.
An anomaly is evidence of difference, not proof of compromise. A backup, application migration, new customer integration, or maintenance event can produce behavior that looks unusual. Equally, an attacker who uses an established administrative path or moves data at a low rate may remain within the expected range.
Detection coverage starts with visibility
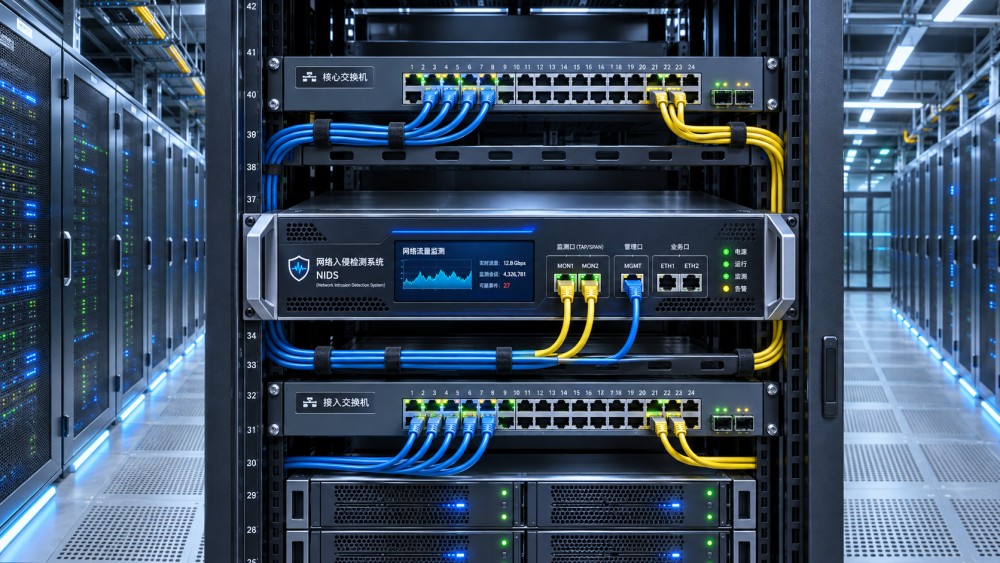
Before comparing detection engines, map the network paths they can actually observe. A sensor at an internet gateway sees different activity from one monitoring traffic between internal workloads. In cloud environments, virtual network architecture, traffic mirroring support, regional boundaries, and processing limits can determine which flows reach the detector. A strong detection method cannot compensate for a path that is not monitored.
Encrypted traffic creates a particularly important distinction. Without decryption, a detector may still inspect metadata such as endpoints, ports, timing, and traffic volume, subject to what the protocol exposes. It cannot reliably apply content-dependent signatures to encrypted payloads it cannot read. Behavioral detection can use the available metadata, but it may lack the context needed to distinguish malicious activity from legitimate encrypted services.
Decryption is not a universal remedy. It requires an appropriate inspection point, key access or proxy architecture, capacity, and a review of privacy and data-handling obligations. Some applications use certificate pinning or encryption arrangements that make interception impractical. Ask suppliers to identify which detections require plaintext, which work on metadata alone, and what visibility is lost when decryption is unavailable.
Packet loss and incomplete sessions also affect both methods. A signature engine may miss a pattern if the relevant packets are absent or stream reconstruction fails. An anomaly model may learn distorted traffic volumes or connection patterns from incomplete data. Evaluation should include sensor placement, peak-load behavior, packet capture quality, and the system’s indication that its input is incomplete.
Where signatures provide a firmer basis for a decision
Signature-based detection is attractive when the organization needs a clear explanation of why an alert fired. A rule match can often be traced to specific protocol fields or observed content, making it easier to validate the event, tune the condition, and communicate the finding to an incident responder.
It is particularly useful where attack indicators are documented and network protocols are well understood. A matching rule can detect repeated exploit attempts without waiting for a behavioral baseline to develop. In a stable environment, a maintained ruleset can provide a practical foundation for identifying activity already represented in that ruleset.
The operational dependency is rule quality and maintenance. A newly disclosed vulnerability does not automatically mean that a useful network signature exists, that it is enabled, or that it applies to the organization’s application version and traffic path. Some vulnerabilities leave no distinctive network pattern; others are visible only at an endpoint or in an application log.
Ask how rules are sourced, tested, delivered, enabled, and retired. Determine whether updates require a restart, whether local rules can be created, and how changes are reviewed. A large signature library is not a meaningful coverage measure without knowing which rules are active, which protocols they inspect, and whether their conditions match the deployed environment.
False positives remain possible. A legitimate payload can resemble an exploit pattern, and a broad rule can match benign administrative or testing activity. Narrowing the rule may reduce noise but also remove coverage. Tuning decisions should therefore record both the alert reduction and the traffic or attack variants that are no longer covered.
When anomaly detection earns its additional complexity
Behavioral detection is useful when the suspicious characteristic is a change in relationships or activity rather than a recognizable payload. For example, an internal host making connections to many previously unseen systems may warrant investigation even if none of those connections matches a specific exploit signature. Unusual outbound transfer patterns may also provide a lead where content is encrypted.
The usefulness of that lead depends on how the baseline is constructed. A detector trained during a quiet period may flag a normal month-end process as exceptional. One trained during a migration may learn temporary behavior as normal. If compromised activity is present during learning, the system may incorporate some of it into its expectation. A baseline should therefore be treated as a maintained security assumption, not a one-time calibration.
Baseline granularity matters. An organization-wide threshold may obscure a sensitive server’s unusual behavior, while a separate model for every short-lived cloud workload may lack enough history to be useful. Peer grouping can help, but only if devices grouped together actually have comparable roles. Ask how the system handles new assets, seasonal activity, maintenance windows, changes in workload ownership, and devices that are frequently offline.
Explanations also vary. “High anomaly score” is not sufficient evidence for a practical response. An alert should show the observed behavior, the expected comparison, the relevant time window, and enough network context to investigate. If a model cannot explain its output in those terms, establish what additional logs or packet evidence will be needed before an analyst can decide whether to escalate.
Anomaly detection should not be equated with automatic detection of zero-day attacks. It can surface previously unseen behavior, but novelty alone is not maliciousness, and an unfamiliar attack need not create a detectable deviation. Its contribution is best assessed against specific attack behaviors and available telemetry, not a general promise to find the unknown.
Compare alert quality using the same workload
A meaningful evaluation uses the same monitored network segments, observation period, asset context, and investigation resources for both approaches. Comparing a signature product configured with a broad ruleset against an anomaly product tuned over several months—or the reverse—says more about test conditions than about detection method.
Build a set of relevant scenarios from the environment: for example, an external exploit attempt against an exposed service, internal scanning, unauthorized remote administration, and unusual outbound transfer. Use safe, authorized simulations or documented historical traffic where appropriate. Include benign changes that could resemble attacks, such as vulnerability scans, deployment activity, and scheduled data transfers. Document which parts of each scenario are visible to the sensor.
Measure detection as more than whether an alert appears. Record whether the alert identifies the affected asset, provides a defensible reason for the finding, reaches the intended workflow, and contains enough evidence to support a decision. A detector that produces a technically correct alert without useful context can still impose substantial investigation work.
Define metrics before testing. For a labeled set of attack scenarios, detection rate is the number detected divided by the number of scenarios in scope. For benign test events, false-positive rate is the number incorrectly alerted on divided by the number of benign events evaluated. Because benign events are far more numerous than attacks in many environments, also record the number of alerts requiring review per day and the share of reviewed alerts judged actionable. State the labeling method and avoid treating unreviewed alerts as confirmed false positives.
Measure investigation time consistently: specify whether the clock starts when the sensor observes traffic or when an alert enters the queue, and whether it ends at initial triage or a documented disposition. Include time spent enriching alerts with asset ownership, authentication records, endpoint activity, or application logs. These dependencies can reverse an apparent advantage in alert volume.
Test the work required to keep detection useful
Signature and anomaly methods shift effort rather than eliminating it. Signature-based deployments need rule updates, exception management, protocol coverage review, and validation after network changes. Behavioral deployments require baseline review, asset classification, threshold adjustment, and investigation of deviations caused by legitimate change. Both need monitoring of sensor health and escalation paths.
Integration should be tested with actual alert records rather than a feature checklist. Confirm that the security information and event management system or case-management platform receives timestamps, source and destination identifiers, detection rationale, severity, and links to supporting evidence. Check whether network address translation, ephemeral IP addresses, or cloud workload changes make it difficult to associate an alert with the responsible asset.
Retention and data access affect the investigation as well. Determine whether the system stores full packets, selected protocol records, flow metadata, or alerts only; each supports a different depth of analysis and carries different storage and privacy implications. Verify export formats, search limits, access controls, and what remains available if the supplier’s service or license is discontinued.
Resource requirements belong in the comparison. Sensor throughput under enabled rules, encrypted traffic processing, packet capture storage, and event ingestion can all affect the deployment design. Request sizing assumptions and test at representative traffic levels, including peaks. A detector that silently drops traffic under load can create a misleading impression of a quieter network.
Choosing a practical combination
A signature-led deployment is a defensible starting point when traffic is visible, the relevant protocols have usable rules, and the immediate requirement is repeatable detection of documented attack patterns. It is less complete where important activity lacks distinctive network indicators or where encrypted payloads conceal the fields those rules need.
Behavioral detection deserves greater weight when the environment can supply consistent traffic context and the security team can investigate deviations. It is especially relevant where the concern is an unusual relationship, volume, or sequence rather than a known payload. Its weaker fit is an environment with unstable asset identity, limited historical data, or no capacity to distinguish operational changes from suspicious events.
Many products combine both methods. That can improve coverage, but the label “hybrid” does not establish that the components share context or that their combined alerts are manageable. Test how a rule match and a behavioral finding are correlated, whether duplicate alerts are merged, and whether disabling one component changes the evidence available to the other.
The strongest selection is the one that detects the organization’s relevant scenarios with observable traffic, explains its findings, and stays operable through ordinary network change. Acceptance should depend on those demonstrated conditions—not on signature counts, model terminology, or a claim that either method can independently detect every intrusion.
Want to dive deeper into these market dynamics, or need data-driven support for your next business move? Drop a line below and let the analysts at CyberTrade provide customized insights.
Related News
 Identity AccessIs Cloud-Hosted RADIUS a Good Fit for Multicloud Enterprises?Posted on Nov 18, 2026Is a cloud-hosted RADIUS server a good fit for a multicloud enterprise? Explore integration, security, resilience, and costs before you decide.
 Identity AccessHow to Test RADIUS Failover Across Cloud RegionsPosted on Nov 18, 2026How do we test RADIUS failover across cloud regions? Follow a practical guide to verify recovery, secure access, audit logs, and failback.
 Identity AccessHow to Choose a Certificate Authority for Multicloud WorkloadsPosted on Nov 18, 2026How do we choose a certificate authority for workloads across multiple clouds? Explore key criteria, compare CA options, and plan a production-ready pilot.
 Multi-CloudHow to Verify CASB Visibility Across Multiple CloudsPosted on Nov 18, 2026How can we verify a CASB's visibility across multiple clouds? Learn to test coverage, trace events, uncover blind spots, and build a reliable assessment.
 Cloud SecurityHow to Test WAF Attack Blocking Without Disrupting Legitimate TrafficPosted on Nov 18, 2026How do we test whether a WAF blocks attacks without disrupting legitimate traffic? Explore safe simulations, false-positive checks, and staged enforcement.
 Identity AccessCan Smart Cards Work With Cloud Apps Without Replacing Your IdP?Posted on Nov 18, 2026Can smart cards work with cloud applications without replacing our identity system? Discover the integration requirements, security benefits, and pilot checks.
 Prices & CostsHow to Compare Cloud HSM Total Costs Across ProvidersPosted on Nov 18, 2026How do we compare the total cost of cloud HSMs across providers? Discover the hidden charges, key assumptions, and practical steps for a fair comparison.
 Multi-CloudHow to Verify Consistent API Gateway Authentication Across CloudsPosted on Nov 18, 2026Verify API gateway authentication across clouds with practical tests for tokens, routes, bypass risks, and policy enforcement. Explore the guide.
 Cloud SecurityDo You Need a Next-Generation Firewall in Every Cloud?Posted on Nov 18, 2026Do we need a next-generation firewall in every cloud environment? Explore traffic risks, cloud-native controls, costs and deployment options.
 Threat ResponseHow to Tell If a Cloud IDS Is Missing TrafficPosted on Nov 18, 2026How can we tell whether an IDS is missing traffic in a cloud environment? Compare flow evidence, test sensor visibility, and uncover hidden coverage gaps.
 Identity AccessHow to check if a certificate authority is trustedPosted on Nov 18, 2026Certificate Authorities aren't trusted equally everywhere. Learn how to check certificate chains, trust stores, and revocation before choosing a CA.
 Cloud SecurityCan cloud access security brokers detect shadow IT?Posted on Nov 18, 2026Cloud Access Security Brokers can uncover shadow IT—but visibility has limits. Discover how CASBs detect cloud apps, expose blind spots, and guide a practical response.











