
Automated Penetration Testing Software: Coverage and Limitations
Automated penetration testing software can identify and sometimes validate exploitable weaknesses across complex environments, but its results are bounded by what it can reach, the identities it can use, and the techniques it is authorized to execute. A clean report is therefore not proof that an environment is secure; it is evidence about a defined set of tests under specific conditions.
The most useful selection question is not how many checks a product advertises. It is whether the product can reproduce relevant attack paths safely, explain what it observed, and distinguish an untested condition from a test that failed to find a weakness.
Coverage starts with reachability, not a feature list
Products use the term “automated penetration testing” for different capabilities. Some primarily discover vulnerabilities and prioritize them according to exploitability. Others attempt controlled exploitation, chain findings into attack paths, or simulate actions after an initial foothold. A product that identifies an exposed service and reports a known vulnerability has not necessarily demonstrated that an attacker can exploit it in the target environment.
Coverage depends on the intersection of several boundaries: the assets in scope, network reachability, available credentials, supported technologies, enabled test modules, and safety restrictions. A tool may support a database platform but test only its network-facing service, not the permissions available to an authenticated database user. Similarly, cloud support may mean configuration assessment through an API rather than validation of whether a particular identity can traverse an access path.
Ask suppliers to describe coverage at the level of the test, not just the asset category. For each relevant environment, establish what the product discovers, which preconditions it checks, what action it takes to validate a finding, and what evidence it retains. Also identify what it cannot inspect without an agent, connector, cloud role, privileged account, or network route.
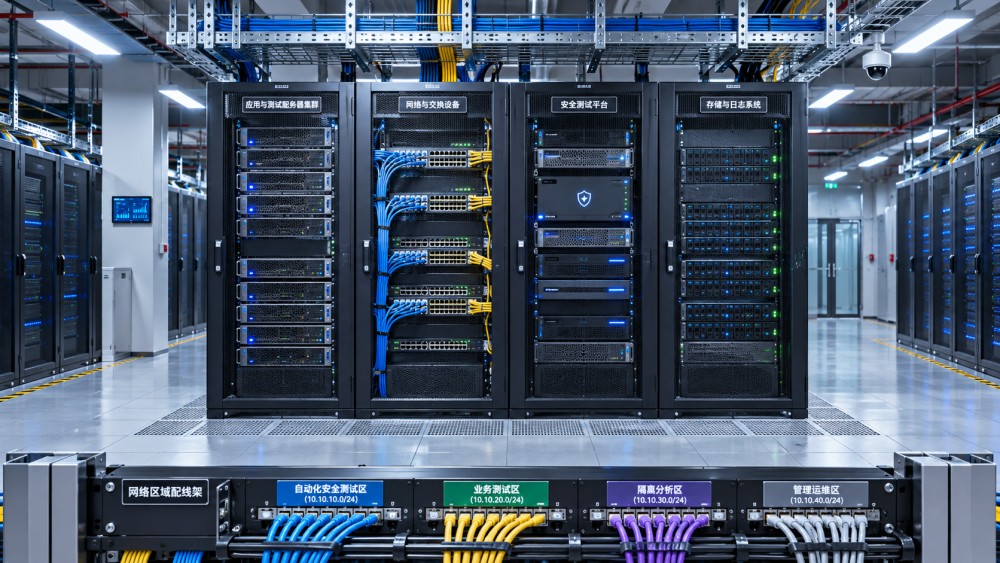
Asset discovery deserves separate attention. If the software cannot see a segmented network, a private cloud endpoint, or an application behind a gateway, the absence of findings there says nothing about its security. Compare discovered assets with an independent inventory, and investigate exclusions and discovery failures before interpreting a low finding count as a positive result.
What automated tests can establish
Automation is particularly useful where security checks can be expressed as repeatable interactions with observable outcomes. Depending on the product and permissions, that can include testing exposed services, identifying known software weaknesses, checking authentication configurations, probing common web application flaws, and validating selected credential or privilege paths.
Evidence strength varies. A version banner associated with a vulnerable release is an indicator, not proof that the vulnerable code is reachable or exploitable. A successful, non-destructive interaction with the affected function is stronger evidence, provided the report explains what happened and rules out alternative explanations. A product should make that distinction visible rather than presenting both results as equally confirmed exploits.
For web applications, testing depth depends heavily on session handling. An unauthenticated scan may cover public pages while missing administrative functions and workflows available only after login. Even with credentials, multifactor authentication, short session lifetimes, single sign-on redirects, and dynamic application states can interrupt coverage. A useful report identifies which roles were tested, whether sessions remained valid, and which application functions were reached.
Internal testing introduces a different set of constraints. A network position with limited access may reveal what an attacker could see from that segment, while a privileged account can expose additional misconfigurations. Neither perspective substitutes for the other. An assessment should record the starting location and identity so that a reported path can be interpreted against a plausible starting condition.
Attack-path claims also require scrutiny. If a tool reports that a user could reach a sensitive system, determine whether it actually exercised each transition or inferred some links from configuration data. An inferred path may be valuable for prioritization, but it is not equivalent to a fully demonstrated sequence. Ask whether the product identifies blocked steps, assumptions, and points where validation stopped.
Where automation leaves material gaps
Business logic is a frequent boundary. A tool may test whether an endpoint accepts an unexpected parameter, yet fail to understand that a discount, approval sequence, or account transfer violates a business rule. These weaknesses depend on the intended behavior of the application, the meaning of its data, and the relationships between users and transactions. Automated requests can assist discovery, but determining impact may require a person who understands the workflow.
Authorization testing has a similar limitation. Detecting that one account can access another account’s object requires representative identities, test data, and knowledge of which access is permitted. A successful response alone does not establish a flaw if the access was authorized; an unsuccessful response does not show that every role and object relationship is protected.
Automation is also constrained by the techniques it knows how to execute. A product may miss a novel exploit chain, a proprietary protocol weakness, or a subtle interaction between controls. Human-led testing can investigate hypotheses outside predefined modules, but it is not exhaustive either. The distinction is practical: automation provides repeatability within its operating boundaries, while skilled testers can adapt their investigation when the environment presents unexpected behavior.
Some activities may be deliberately excluded. Password spraying, disruptive payloads, destructive actions, social engineering, and post-compromise operations can create operational or legal risks. A product’s inability or refusal to perform them under a chosen policy is not necessarily a defect. It becomes a problem when the final report fails to show that those techniques were excluded.
Validation must be balanced against production safety
The strongest practical evidence often comes from exercising a weakness, but exploitation can change data, exhaust resources, trigger security controls, or interrupt a fragile service. Supplier descriptions such as “safe exploitation” are not sufficient on their own. Establish what each test does, whether it writes files or changes configuration, how it cleans up, and what happens if execution is interrupted.
For production systems, define permitted targets, time windows, rate limits, escalation contacts, and stop conditions before a pilot. Where a system cannot tolerate active exploitation, a less intrusive check or a representative non-production environment may be appropriate. The result should then be labelled accordingly: a finding inferred from a production configuration or demonstrated in a test environment is not the same as an exploit confirmed against the production asset.
Non-production results also have transfer limits. Different software versions, network controls, data, identity permissions, or security monitoring can change the outcome. Record those differences rather than assuming that a successful test in staging proves the same path exists in production.
Check how the platform handles operational safeguards. Can specific assets or modules be excluded? Can testing be paused immediately? Are rate limits applied per target as well as globally? Does the tool log actions in enough detail to distinguish its activity from a genuine incident? These controls matter as much as test breadth when assessment must coexist with business operations.
Interpreting findings without overstating assurance
A finding should show the affected asset, test time, starting position, account or role used, observed behavior, and the evidence supporting the conclusion. It should also describe the validation method and any assumptions. For an authenticated web test, for example, a response captured after a session expired is not reliable evidence about what the intended role could access.
Separate at least three outcomes: a weakness confirmed under the test conditions, an indication requiring further validation, and a test that could not be completed. A timeout, inaccessible endpoint, rejected credential, or unsupported application flow belongs in the third category, not in a clean bill of health. The ability to export these statuses is important when evidence is reviewed outside the product interface.
False positives consume remediation time, but false negatives are harder to see. A tool can produce a precise-looking report while silently missing assets, roles, or application states. Review coverage logs and failures alongside findings. If the platform reports only successful checks, ask how an operator can determine which intended tests never ran.
Retesting should demonstrate that the relevant condition changed, not merely that the original alert disappeared. A credential may have expired, a target may be unreachable, or a module may have failed to execute. A useful retest links the new evidence to the original asset and test conditions and flags material differences between runs.
Designing a pilot that can distinguish products
A pilot is most informative when it represents the environment the software will actually assess. Include a limited set of authorized assets with different characteristics: an externally exposed service, an authenticated application, and an internal or cloud resource where relevant. Define known test conditions and expected evidence in advance, while preserving safeguards for any production targets.
Use the same scope, starting positions, credentials, network access, and test windows when comparing products. If one product receives broader privileges or connectivity, record that difference rather than attributing all result differences to detection quality. Where identical conditions are impossible, compare each result against the access and configuration that produced it.
Evaluation should examine more than the number of findings:
- Discovery and execution: Which in-scope assets were discovered, which tests ran, and what prevented the rest?
- Evidence quality: Can a reviewer reproduce or independently assess a finding without relying solely on a severity label?
- Validation depth: Did the product confirm exploitation, verify a precondition, or infer risk from configuration?
- Operational control: Were scope restrictions, rate limits, exclusions, and stop procedures effective?
- Remediation workflow: Can findings be assigned, deduplicated, exported, and retested without losing their original context?
A controlled set of known weaknesses can test whether expected findings appear, but it should include relevant negative cases as well: configurations that resemble weaknesses but are not exploitable under the stated conditions. This exposes imprecise reporting. It does not establish a universal detection rate; the result applies to the selected cases, product configuration, and test period.
Integration and operating requirements can narrow usable coverage
A product may be technically capable of testing a resource but unable to do so within the organization’s access model. Clarify whether deployment requires an internal appliance, agent, hosted service, or connector; which outbound connections are needed; and how the platform reaches segmented networks. Review whether cloud permissions are read-only or allow test actions, and whether privileges can be scoped to selected accounts and resources.
Credentials and evidence introduce their own controls. Determine where secrets are stored, how they are rotated, whether service accounts can be restricted, and who can retrieve captured request and response data. Reports may contain hostnames, user identifiers, tokens, screenshots, or application content. Data location, retention, deletion, and access controls should match the sensitivity of the assessment material.
Integration with ticketing, vulnerability management, and security monitoring should preserve context rather than export only a title and severity. Check whether repeated scans create duplicate tickets, how resolved findings are reopened, and whether test activity can be identified in logs. Account for the staff time needed to maintain connectors, renew credentials, update scope, review inconclusive results, and investigate false positives; licensing alone does not describe the operating commitment.
The strongest choice is the one whose demonstrated coverage matches the intended use. For recurring checks across stable, reachable assets, repeatability and reliable retesting may carry substantial weight. For applications with complex authorization or critical workflows, automated results are more useful when paired with targeted human investigation. In either case, acceptance should depend on evidence of tests actually performed, explicit exclusions, and a workable process for resolving what the software leaves uncertain.
Want to dive deeper into these market dynamics, or need data-driven support for your next business move? Drop a line below and let the analysts at CyberTrade provide customized insights.
Related News
 Identity AccessIs Cloud-Hosted RADIUS a Good Fit for Multicloud Enterprises?Posted on Nov 18, 2026Is a cloud-hosted RADIUS server a good fit for a multicloud enterprise? Explore integration, security, resilience, and costs before you decide.
 Identity AccessHow to Test RADIUS Failover Across Cloud RegionsPosted on Nov 18, 2026How do we test RADIUS failover across cloud regions? Follow a practical guide to verify recovery, secure access, audit logs, and failback.
 Identity AccessHow to Choose a Certificate Authority for Multicloud WorkloadsPosted on Nov 18, 2026How do we choose a certificate authority for workloads across multiple clouds? Explore key criteria, compare CA options, and plan a production-ready pilot.
 Multi-CloudHow to Verify CASB Visibility Across Multiple CloudsPosted on Nov 18, 2026How can we verify a CASB's visibility across multiple clouds? Learn to test coverage, trace events, uncover blind spots, and build a reliable assessment.
 Cloud SecurityHow to Test WAF Attack Blocking Without Disrupting Legitimate TrafficPosted on Nov 18, 2026How do we test whether a WAF blocks attacks without disrupting legitimate traffic? Explore safe simulations, false-positive checks, and staged enforcement.
 Identity AccessCan Smart Cards Work With Cloud Apps Without Replacing Your IdP?Posted on Nov 18, 2026Can smart cards work with cloud applications without replacing our identity system? Discover the integration requirements, security benefits, and pilot checks.
 Prices & CostsHow to Compare Cloud HSM Total Costs Across ProvidersPosted on Nov 18, 2026How do we compare the total cost of cloud HSMs across providers? Discover the hidden charges, key assumptions, and practical steps for a fair comparison.
 Multi-CloudHow to Verify Consistent API Gateway Authentication Across CloudsPosted on Nov 18, 2026Verify API gateway authentication across clouds with practical tests for tokens, routes, bypass risks, and policy enforcement. Explore the guide.
 Cloud SecurityDo You Need a Next-Generation Firewall in Every Cloud?Posted on Nov 18, 2026Do we need a next-generation firewall in every cloud environment? Explore traffic risks, cloud-native controls, costs and deployment options.
 Threat ResponseHow to Tell If a Cloud IDS Is Missing TrafficPosted on Nov 18, 2026How can we tell whether an IDS is missing traffic in a cloud environment? Compare flow evidence, test sensor visibility, and uncover hidden coverage gaps.
 Identity AccessHow to check if a certificate authority is trustedPosted on Nov 18, 2026Certificate Authorities aren't trusted equally everywhere. Learn how to check certificate chains, trust stores, and revocation before choosing a CA.
 Cloud SecurityCan cloud access security brokers detect shadow IT?Posted on Nov 18, 2026Cloud Access Security Brokers can uncover shadow IT—but visibility has limits. Discover how CASBs detect cloud apps, expose blind spots, and guide a practical response.











